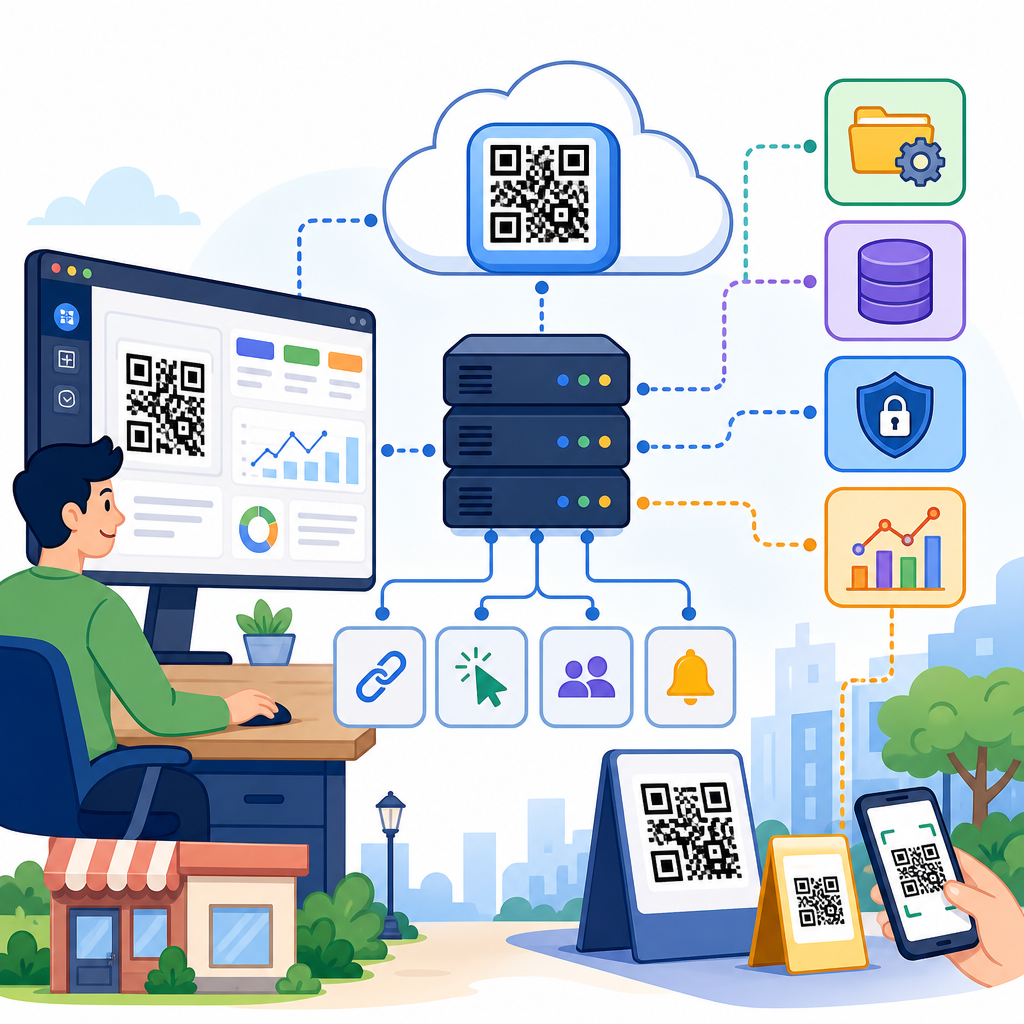
A QR code management system is the software and infrastructure layer that creates, stores, tracks, secures, and updates QR codes at scale. It goes far beyond generating a single black-and-white square. In practice, a robust system handles code issuance, destination routing, campaign governance, analytics collection, access control, error recovery, and integrations with business platforms. When organizations print thousands of codes across packaging, retail displays, manuals, tickets, and equipment labels, the architecture behind those codes determines whether the program remains reliable or becomes an operational liability.
I have worked on QR implementations for marketing teams, manufacturers, and internal asset programs, and the pattern is consistent: the visible code is the simplest part. The difficult work happens behind the scenes. Teams need to decide whether a code is static or dynamic, how redirects will be resolved, where scan events will be logged, how destinations can be updated without reprinting materials, and how malicious tampering will be detected. Those decisions affect uptime, security, data quality, and long-term maintenance costs.
For clarity, a static QR code directly encodes final data such as a URL, contact card, or Wi-Fi credential. A dynamic QR code usually encodes a short URL or identifier that points to a managed service, allowing the destination to change later. Most enterprise QR code management systems center on dynamic codes because they support governance and measurement. They also allow practical business workflows such as redirecting product packaging to different regional pages, pausing expired promotions, or routing scans to fallback content if a landing page is unavailable.
This matters because QR has matured from a convenience feature into a core interface between physical and digital channels. Consumers scan shelf talkers, restaurant menus, event badges, and medical device labels. Field technicians scan equipment tags to open maintenance records. Logistics teams scan bins and pallets to trigger workflows. In each case, the QR code is only the entry point. The real value comes from a management system that can reliably connect scans to business logic, report outcomes, and support continuous updates. Building QR code systems well requires an architecture that is scalable, observable, secure, and easy for nontechnical teams to operate.
Core components of a QR code management system
At a high level, the architecture usually includes six layers: generation, registry, resolution, destination delivery, analytics, and administration. The generation layer creates payloads and renders images in formats such as PNG, SVG, EPS, or PDF. The registry stores metadata about each code, including its owner, campaign, destination rules, status, creation date, and print version. The resolution layer receives the scan request and determines what should happen next. The destination delivery layer either redirects the user or returns app-specific content. Analytics capture the scan event and contextual attributes. Administration provides user interfaces, APIs, permissions, and audit logs.
The registry is the heart of the system. Every QR code should have a durable unique identifier, not just a destination URL. In production systems, I prefer immutable code IDs with mutable routing records. That separation avoids breaking references when business users update campaigns. A common model stores entities such as organization, workspace, campaign, QR asset, redirect rule, destination, event, and user. This makes reporting easier because one code can belong to a campaign, while the same destination can serve multiple codes, and historical redirect changes can be preserved for auditing.
The resolution service should be treated as critical infrastructure. It needs low latency, strong caching, and graceful degradation. If a physical package in a store points to your redirect domain, every scan depends on that endpoint. Mature implementations use a globally distributed content delivery network, HTTPS everywhere, automated certificate management, health checks, and a stateless redirect service backed by a fast datastore such as Redis, DynamoDB, or a well-indexed relational database. The goal is simple: return the correct destination in milliseconds while recording enough event data for analytics.
Administration is where adoption succeeds or fails. Marketing teams need bulk creation, editable destinations, and naming conventions. Operations teams need lifecycle controls such as activate, deactivate, archive, and clone. Security teams need role-based access control, single sign-on, and audit trails. Developers need APIs and webhooks. If the admin layer is weak, business users bypass the platform by generating unmanaged codes with random tools, which creates broken customer journeys and no governance.
Data model, identifiers, and lifecycle design
A well-designed data model prevents future rework. Every code should have at least four identifiers: an internal primary key, a public code ID, a short path or token used in the QR payload, and a campaign or asset reference for reporting. The public code ID should be non-sequential if codes are externally visible, because predictable identifiers invite enumeration. UUIDs, ULIDs, or short random tokens are common choices. If compactness matters for dense print scenarios, the payload can use a short token while the system maps it back to richer metadata internally.
Lifecycle design is equally important. In real deployments, codes move through draft, approved, generated, printed, active, paused, expired, and archived states. Those states should be explicit in the data model and enforced in the interface and API. For example, a printed code may allow destination edits but not payload changes, because changing the payload would invalidate the physical print. I have seen teams overlook this distinction and accidentally regenerate a code image after products were already boxed, creating a mismatch between the stored asset and the item in circulation.
Versioning matters whenever a destination, design, or tracking configuration changes. Rather than overwriting records, production systems should preserve revision history with timestamps and user attribution. This supports troubleshooting when scan volume drops after an edit or when a regional redirect rule was changed incorrectly. It also helps with regulated environments, where organizations may need evidence of what content a code pointed to on a specific date.
Multi-tenancy deserves careful planning if the platform serves several brands, regions, or clients. Tenant isolation can be logical or physical, but permissions, rate limits, storage paths, and analytics views must respect those boundaries. A manufacturer running consumer packaging codes and internal maintenance labels may use the same platform, yet the data retention, access rights, and destination domains should differ. Designing for tenancy early is easier than bolting it on later.
Dynamic routing, redirects, and destination logic
Dynamic routing is the main reason organizations adopt a QR code management system. Instead of embedding the final destination directly, the QR code points to a managed URL that can evaluate rules before redirecting. Those rules may depend on geography, language, device type, campaign dates, product SKU, inventory status, or app install state. A beverage brand, for example, can print one code on packaging and route scanners in Canada to English or French pages while sending users in Germany to a compliance-specific landing page.
Redirect behavior should be deterministic and testable. I recommend a rule engine with clear precedence: exact code override, campaign rule, locale rule, platform rule, then default destination. Keep the chain short. Complex nested logic becomes hard to debug, especially during high-traffic campaigns. Use HTTP 302 or 307 redirects for mutable destinations and reserve 301 redirects for truly permanent moves. Browser caching of 301 responses can create long-lived errors when business users later change routing rules.
Mobile app deep linking introduces another layer. A scan may open a native app if installed, fall back to an app store if not, or display a mobile web page instead. Universal Links on iOS and App Links on Android should be part of the design, not an afterthought. If the use case depends on authenticated in-app actions, define a fallback experience for users whose devices block automatic app opening or whose enterprise browsers alter redirect handling.
Reliability features make a measurable difference. The resolver should support fallback destinations, timeout thresholds, and circuit breakers if downstream services fail. For example, if a personalization service is unavailable, the platform can still send users to a generic landing page instead of returning an error. This is one of the most practical distinctions between a hobby QR generator and an enterprise-grade QR code management system.
Analytics, observability, and performance architecture
Scan analytics are valuable only when the event model is consistent. At minimum, log code ID, timestamp, resolved destination, HTTP status, user agent, referrer when available, IP-derived geography, and rule path taken. Separate raw event collection from reporting aggregates. Raw events support audits and reprocessing, while aggregates power dashboards. In systems I have built, the common stack is an edge logger or application event stream feeding a warehouse such as BigQuery, Snowflake, or Redshift, with dashboard summaries materialized on schedule.
It is important to distinguish scan count from unique visitors and from successful conversions. A single user may scan several times because of weak connectivity, camera hesitation, or packaging glare. Some privacy features also limit attribution precision. Present these metrics clearly so stakeholders do not overinterpret top-line scan volume. A campaign with fewer scans but higher destination engagement may be stronger than one with large raw traffic and immediate bounces.
Observability should cover both system health and business outcomes. Technical telemetry includes request latency, redirect error rate, cache hit ratio, DNS performance, certificate expiry, and regional availability. Business telemetry includes scan volume by code, destination completion rate, broken-link detection, and anomaly alerts. If a code printed on a product line suddenly returns 404 responses after a CMS change, the issue should be visible within minutes, not after customer complaints.
| Layer | Primary Responsibility | Typical Tools | Key Risk |
|---|---|---|---|
| Generation | Create payloads and render code assets | ZXing, qrcode, ImageMagick | Unreadable design or wrong error correction |
| Registry | Store metadata, ownership, and status | PostgreSQL, MySQL, DynamoDB | Weak versioning and poor tenant isolation |
| Resolution | Match token to routing logic and redirect | Node.js, Go, Redis, CDN edge functions | Latency, downtime, redirect loops |
| Analytics | Capture and aggregate scan events | Kafka, BigQuery, Snowflake, Looker | Inconsistent event schema |
| Administration | Manage users, campaigns, and audits | React, SSO, RBAC services | Unauthorized edits and poor usability |
Performance tuning begins with minimizing resolver work. Avoid expensive joins on every scan. Precompute active routing records, cache code metadata near the edge, and use asynchronous pipelines for nonessential tasks such as enrichment. If the system serves global packaging, benchmark scans from multiple regions and validate p95 latency, not only average latency. Scanners are often on mobile connections, so every redirect hop matters.
Security, compliance, and governance controls
QR systems are attractive targets because users trust printed codes. Attackers may place counterfeit stickers over legitimate labels, exploit open redirects, or abuse unmanaged code generators to route traffic to phishing pages. The management system must reduce those risks. Start with domain control. Use branded, HTTPS-protected short domains and allow redirects only to approved destinations or validated domain patterns. Open redirect behavior should be blocked by default.
Administrative security should include single sign-on, multi-factor authentication, role-based access control, and detailed audit logging. Separate roles for creators, approvers, publishers, and analysts are useful when codes appear on packaging or regulated materials. In one manufacturing environment, we required two-person approval before activating destinations tied to serialized equipment labels, because an incorrect redirect could mislead technicians during maintenance.
Privacy and compliance depend on jurisdiction and use case. If scan data can be linked to individuals, the platform may fall under GDPR, CCPA, or sector-specific requirements. IP addresses, device fingerprints, and exact locations should be handled carefully, with clear retention rules and lawful bases for processing. Many organizations do not need personally identifiable data to gain value from QR analytics. Aggregate reporting is often sufficient and less risky.
Governance also includes naming standards, domain ownership, print approval workflows, and retirement policies. Codes on durable assets may remain in the field for years, so the redirect domain and routing service need long-term stewardship. A common failure pattern is launching a campaign on a temporary subdomain owned by one team, then discovering two years later that the certificate expired and nobody maintains the DNS zone. Good architecture anticipates that physical codes often outlive digital projects.
Integration patterns and implementation choices
A QR code management system becomes far more useful when it connects to surrounding platforms. Common integrations include content management systems for landing pages, CRM platforms for campaign attribution, product information management systems for SKU-linked content, mobile apps for deep links, and ERP or asset systems for equipment records. Webhooks are practical for notifying downstream tools when a code is created, activated, or scanned above a threshold. APIs are essential for bulk operations and automation.
Build-versus-buy decisions depend on scale and control requirements. Off-the-shelf platforms are faster for marketing campaigns and standard analytics. Custom systems make sense when QR is embedded in core operations, when governance is strict, or when codes need to trigger proprietary workflows. I usually advise teams to map their nonnegotiables first: redirect logic complexity, domain control, data residency, API depth, labeling integrations, and retention requirements. That exercise reveals whether a managed platform will suffice or whether a custom architecture is justified.
Implementation should proceed in phases. Start with a narrow but production-grade foundation: token generation, branded redirect domain, metadata registry, basic analytics, and admin approvals. Next add rule-based routing, bulk import, design templates, and dashboards. Later phases can introduce deep linking, experimentation, fraud signals, and advanced warehouse integrations. This staged approach avoids overengineering while keeping the core architecture clean.
The central lesson in building QR code systems is that success depends on disciplined architecture, not on code generation alone. Treat QR as a durable digital entry point tied to real business processes. Design the registry carefully, keep redirect logic simple and fast, capture analytics with a consistent schema, secure every administrative and public interface, and plan for the long life of printed materials. If you are building or modernizing a QR code management system, start by auditing your current code inventory, redirect domains, and governance gaps, then define the architecture that can support scale without losing control.
Frequently Asked Questions
What is the core architecture of a QR code management system?
The core architecture of a QR code management system usually combines several coordinated layers rather than a single QR code generator. At the front end, there is an interface or API where users, internal teams, or connected business systems request new QR codes, update destinations, manage campaigns, and review analytics. Behind that sits an application layer that handles business logic such as code creation rules, redirect behavior, expiration settings, ownership, approval workflows, and permissions. A storage layer keeps records for the QR code itself, the short link or token behind it, metadata such as campaign names and asset IDs, scan history, and audit logs. A routing layer resolves scans in real time, determining where each code should send the user based on current rules, geography, device type, language, or campaign status. Finally, the system often includes analytics pipelines, monitoring tools, security controls, and integrations with CRM, ERP, marketing automation, inventory, and support platforms. In a mature deployment, the architecture is designed for scale, reliability, and governance so organizations can manage thousands or millions of codes consistently across packaging, retail displays, manuals, tickets, and equipment.
Why do organizations use dynamic QR codes instead of static QR codes in a management system?
Organizations typically rely on dynamic QR codes because they separate the printed code from the final destination, which creates far more flexibility and control. With a static QR code, the encoded destination is permanent. If a URL changes, a product page moves, a campaign ends, or a support document is updated, the printed code may become obsolete. A dynamic system solves that by encoding a managed redirect or short identifier instead of the final destination itself. When someone scans the code, the request first reaches the QR code management system, which then routes the user to the correct destination based on current settings. That architecture allows teams to update links after printing, run time-based promotions, localize by region or language, conduct A/B tests, disable compromised codes, and recover quickly from content or operational changes. It also makes analytics possible, since the system can record scan events before forwarding the user. In large-scale environments, this dynamic model is what turns QR codes from simple images into governed digital assets that can be maintained, measured, and secured over time.
How does a QR code management system handle routing, tracking, and analytics at scale?
At scale, routing, tracking, and analytics depend on an efficient scan-resolution workflow and a reliable event collection pipeline. When a person scans a code, the request is typically sent to a redirect service optimized for speed and uptime. That service looks up the code identifier in a database or cache, evaluates the routing rules, and sends the user to the correct destination. Those rules may include status checks, expiration windows, geographic mapping, device detection, language preferences, campaign segmentation, or fallback destinations if a page is unavailable. At the same time, the system records scan data such as timestamp, approximate location, device type, browser, referrer context when available, and the specific QR asset or campaign involved. In high-volume systems, analytics events are often written asynchronously to queues or streaming platforms so the redirect remains fast while data is processed downstream. Reporting layers then aggregate the raw events into dashboards for marketers, operations teams, and product owners. This architecture helps organizations understand engagement patterns, detect anomalies, compare campaign performance, and make decisions about content placement, packaging, retail execution, and customer journeys without slowing down the user experience.
What security and governance features are important in a QR code management system?
Security and governance are essential because a QR code often acts as a public entry point into business systems, customer experiences, and operational processes. A robust platform should include role-based access control so only authorized users can create, edit, approve, or deactivate codes. Audit logs are important for tracking who changed a destination, when the change occurred, and what the previous configuration was. Approval workflows help prevent accidental edits, especially in regulated industries or large distributed organizations. On the technical side, the system should enforce HTTPS, protect APIs with authentication and rate limiting, validate destination URLs, and monitor for suspicious redirect patterns or abuse attempts. Many organizations also need versioning and rollback capabilities so they can quickly recover from a misconfiguration. Governance features usually include naming conventions, campaign tagging, lifecycle states, expiration policies, ownership assignment, and archival rules. Together, these controls reduce the risk of broken links, malicious redirects, unauthorized changes, and compliance failures. In practice, the strongest QR code management systems treat every code as a managed digital asset with clear accountability from creation through retirement.
How does a QR code management system integrate with broader business and operational platforms?
Integration is one of the main reasons organizations invest in a dedicated QR code management system rather than using standalone generators. In a modern architecture, QR codes are often tied to products, packaging runs, service manuals, tickets, support cases, store displays, inventory records, field equipment, and marketing campaigns. To support those use cases, the system may connect with product information management tools, content management systems, CRM platforms, marketing automation suites, ERP systems, inventory software, e-commerce platforms, and customer support applications. These integrations allow QR codes to be created automatically when new assets are published, updated when product pages change, linked to serialized items, or associated with campaign reporting in other analytics environments. For operational teams, integrations can streamline governance by syncing owners, approval states, and metadata across platforms. For customer-facing experiences, they enable destination personalization, localized content delivery, and closed-loop measurement between scans and downstream actions such as signups, purchases, service requests, or documentation views. In architectural terms, integrations turn the QR code management system into a connective layer between physical touchpoints and digital business systems, which is what makes large-scale QR deployments practical, measurable, and maintainable.