QR code redirect logic is the routing layer that decides what happens after a person scans a code, and in any serious deployment it matters more than the image itself. In practical terms, a static QR code stores a fixed destination, while a dynamic QR code points to a controllable short URL that can redirect by rule, device, location, language, campaign, or time. When I build QR code systems for product packaging, event operations, and retail signage, the redirect service is always the operational core because it determines analytics quality, campaign flexibility, uptime, and governance. This topic matters to any team working on QR Code Technology & Development because the scan experience now sits at the intersection of marketing attribution, mobile web performance, privacy compliance, and backend reliability. A well-designed QR code system must do four things at once: resolve quickly, route accurately, measure consistently, and fail safely. If any of those break, the business sees misattributed traffic, broken customer journeys, or printed assets that cannot be corrected after distribution. Building QR code systems therefore means thinking beyond code generation to architecture, data models, redirect rules, observability, and security. The sections below explain how to implement QR code redirect logic as a durable hub foundation, using the standards, tools, and patterns that experienced teams rely on in production.
Core Architecture for Building QR Code Systems
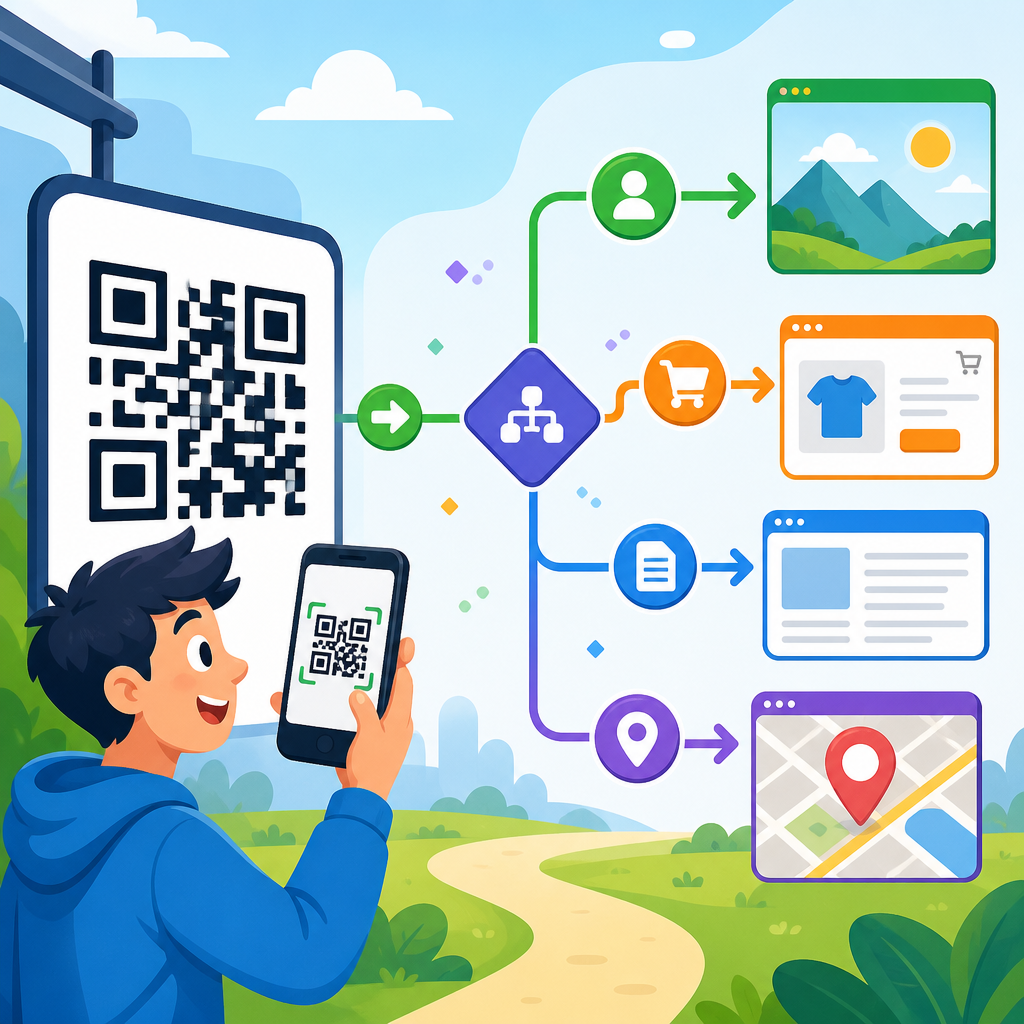
The simplest reliable pattern is this: encode a short HTTPS URL in the QR code, receive the request at an edge or application layer, evaluate redirect rules, log the scan event, and return an HTTP redirect to the final destination. I strongly recommend HTTPS-only links, canonical hostnames, and permanent ownership of the redirect domain because printed codes can stay in circulation for years. In production, I usually separate four components: a code registry, a rule engine, an analytics pipeline, and an admin interface. The registry stores the QR identifier, campaign metadata, destination history, status, and ownership. The rule engine evaluates conditions such as operating system, country, language, and date range. The analytics pipeline records scan data asynchronously to avoid slowing redirects. The admin layer controls edits, approvals, and audit logs.
For redirect behavior, use HTTP status codes deliberately. A 302 or 307 temporary redirect is best when destinations may change, while 301 or 308 is appropriate only when the mapping is truly permanent and you are comfortable with downstream caching. For app deep links, most teams use a web fallback page because native schemes and universal links can fail differently across iOS and Android. Cloudflare Workers, Fastly Compute, AWS Lambda with API Gateway, NGINX, and traditional application frameworks can all run the logic. The decision should depend on latency targets, regional traffic, and operational skills. A high-volume packaging program often benefits from edge execution, while an internal event system may be fine on a conventional web stack.
Designing Redirect Rules and Destination Logic
Good redirect logic starts with explicit precedence. If the same scan qualifies for several rules, your system must resolve them consistently. A common order is: code status check, expiration logic, abuse filtering, explicit campaign override, device rule, locale rule, geography rule, time window, then default fallback. That order prevents accidental conflicts and makes debugging easier. For example, a restaurant chain may route French-speaking users in Quebec to a bilingual menu, Android users to Google Play for the loyalty app, and everyone else to a seasonal promotion. Without precedence, one rule can unexpectedly shadow another.
Rule conditions should be based on signals you can obtain reliably from a web request. Device detection usually depends on the user agent, but treat it as probabilistic because strings change and browsers reduce detail. Language can be inferred from the Accept-Language header, yet users may scan while traveling, so always provide an accessible selector on the landing page. Geography is typically derived from IP intelligence from providers such as MaxMind or ipinfo, but it should be coarse enough to respect privacy expectations and account for VPN use. Time-based logic is straightforward and useful for expiring event check-ins or switching campaigns at midnight local time, but store time zones explicitly to avoid errors around daylight saving changes.
One of the biggest implementation mistakes is treating every code as a unique logic container. In maintainable systems, rules are reusable objects attached to campaigns, products, or environments. I prefer a hierarchy where a code inherits defaults from an organization, campaign, or template, then optionally adds overrides. That approach reduces configuration drift and makes QA practical. It also supports internal linking across the broader documentation set: teams can connect this hub page to more specific articles on analytics, security, mobile deep linking, and QR code generation without duplicating logic definitions.
Data Model, APIs, and Administrative Controls
A production-grade data model needs more than an ID and a URL. At minimum, store: qr_id, public_slug, current_destination, destination_history, rule_set_id, owner_team, status, created_at, updated_at, expires_at, checksum, and print_batch. If the system supports regulated workflows, add approval_state, approver_id, and change_ticket. I also recommend storing a human-readable label and a machine-safe immutable primary key. The label helps support teams identify assets quickly, while the immutable key prevents accidental breakage when marketing names change.
APIs should be versioned from the beginning. In practice, teams eventually need bulk creation, partial updates, rule simulation, destination validation, archive endpoints, and webhooks for downstream analytics or content management. A useful pattern is to separate public resolution endpoints from authenticated management endpoints. The resolver should be optimized for speed and resilience, with strict payload minimization. The management API can support richer validation and pagination. Role-based access control is essential. I have seen expensive packaging reruns caused by a broad editor role that allowed unreviewed destination changes. Basic controls such as two-person approval for live redirects, change diffs, and audit logging pay for themselves quickly.
| Component | Purpose | Implementation Notes |
|---|---|---|
| Short URL Resolver | Receives scan and issues redirect | Keep latency low, cache rule lookups, return 302 or 307 by default |
| Rule Engine | Evaluates device, locale, geography, and time conditions | Define deterministic precedence and test conflicts |
| Registry Database | Stores code records, metadata, and history | Use immutable IDs, status fields, and audit trails |
| Analytics Pipeline | Captures scan events for reporting | Log asynchronously to avoid slowing user redirects |
| Admin Console | Manages creation, edits, approvals, and permissions | Use role-based access control and validation guardrails |
Analytics, Attribution, and Measurement Quality
Redirect logic is the natural collection point for scan analytics because every dynamic QR code request passes through it. That does not mean every scan equals a meaningful session, so your event model should distinguish scan, redirect, landing page view, and conversion. I typically log timestamp, qr_id, resolved_rule, HTTP status, referer when present, user agent, coarse geolocation, and a request identifier for traceability. Then I connect that request identifier to downstream page analytics using query parameters or server-side event stitching. UTM parameters still matter because many teams report in Google Analytics 4, Adobe Analytics, or attribution warehouses that rely on campaign dimensions.
Measurement quality improves when you standardize naming conventions. Decide early whether campaign values will reflect print channel, asset type, region, or promotion. Keep them short and documented. In retail, for example, I often use source=qr, medium=packaging, campaign=summer_launch, content=flavor_a_endcap. That structure enables comparison between shelf talkers, cartons, and window decals. Be careful with duplicate counting. Mobile browsers, messaging apps, and security scanners can generate prefetches or repeated requests. Mitigations include bot filtering, user-agent classification, short deduplication windows, and a distinction between raw scans and modeled unique scans. Your reports should explain the difference clearly, especially when executives compare printed campaign performance with paid media dashboards.
Performance, Reliability, and Operational Resilience
People experience redirect systems in fractions of a second, so performance engineering matters. A practical target is to keep median redirect handling under 100 milliseconds at the edge and under 300 milliseconds end to end before the destination starts loading. The easiest gains come from avoiding synchronous database writes on the request path, caching code records by slug, and keeping rule evaluation lightweight. If you need heavy personalization, redirect to a fast landing page and let that page do additional rendering, rather than bloating the resolver.
Reliability requires planning for failure modes that are easy to overlook. DNS expiration, certificate lapses, deleted landing pages, and unpublished CMS content break QR journeys silently until someone scans a printed asset in the field. I always add destination health checks, synthetic scanning tests, and alerts for spike anomalies or rising 404 rates. For major launches, create a rollback destination that can be activated globally if a microsite fails. Multi-region infrastructure helps for national or international campaigns, but operational discipline matters more than platform choice. Document runbooks for expired campaigns, compromised destinations, and after-hours escalations. If the code is printed on packaging or installed signage, assume support windows longer than the marketing calendar.
Security, Privacy, and Compliance Considerations
QR redirects sit in a risk-sensitive position because users often cannot see the final destination before opening it. The system should protect both the business and the scanner. Validate destinations on creation, restrict allowed schemes to HTTPS, and block private-network targets, localhost references, and dangerous parameters. If your organization permits external URLs, use allowlists by team or campaign type. Phishing risk is real: a compromised admin account can weaponize a widely distributed code. Strong authentication, approval workflows, signed change logs, and anomaly detection reduce that risk substantially.
Privacy design should be intentional. In many jurisdictions, IP addresses and device identifiers can be personal data when combined with other fields. The safest practice is to collect only what is needed for operational analytics, aggregate where possible, and define retention limits. If you enrich geolocation, prefer country or region over precise coordinates unless there is a clear, documented need. Consent obligations depend on what happens after the redirect as much as inside it, so coordinate with legal and analytics teams. Accessibility also belongs here. Redirect landing pages should support readable contrast, keyboard navigation, clear language selection, and fast mobile loading. A QR code system is only successful if the destination experience is usable for the broad audience that scans it.
Testing, Governance, and Long-Term Maintenance
The best QR code systems are boring in production because teams test them relentlessly before print. My standard process includes unit tests for rule precedence, integration tests for resolver endpoints, device-specific manual scans on iOS and Android, and preflight checks for every destination before files go to press. Test with multiple scanner apps because embedded camera behavior differs by device and OS version. Verify that redirects behave the same on cellular and Wi-Fi networks, and that deep-link fallbacks do not trap users in app-store loops. If the QR code will appear on curved packaging, glossy material, or low-light signage, test the physical print as carefully as the URL logic.
Governance is what turns a one-off redirect script into a sustainable platform. Establish naming standards, ownership rules, approval thresholds, and deprecation policies. Decide who may create codes, who may edit live destinations, and how retired campaigns are archived. I advise teams to maintain a content inventory tied to print batches so they can answer a simple but critical question: where is this code physically deployed? Without that record, a redirect change can unintentionally affect inventory still on shelves. Long-term maintenance also means writing companion articles and internal guides for related parts of Building QR Code Systems, including code generation standards, print contrast and size guidelines, deep linking methods, analytics setup, and security reviews. This hub article should anchor that documentation set, because redirect logic is the control plane that connects all of those disciplines.
Implementing QR code redirect logic correctly means treating the QR image as the entry point, not the product. The real system is the resolver, the rule engine, the analytics model, the admin controls, and the operational safeguards that keep scans fast and trustworthy after assets are printed. The most effective approach is straightforward: use dynamic short URLs, evaluate deterministic rules, log events asynchronously, secure destination changes, and test every scenario that could occur in the field. When teams follow that pattern, they gain flexibility to update campaigns without reprinting, improve attribution accuracy, and reduce the risk of broken customer journeys. They also create a scalable foundation for the wider Building QR Code Systems discipline, from packaging programs to event check-ins and omnichannel retail experiences. If you are building out this sub-pillar, start by documenting your redirect architecture, rule precedence, and governance model, then connect this hub to the deeper implementation guides your team needs next.
Frequently Asked Questions
What is QR code redirect logic, and why is it more important than the QR code image itself?
QR code redirect logic is the decision-making layer that determines where a user goes immediately after scanning a code. The printed QR image is simply the entry point. In a basic setup, the code contains a fixed URL and always sends every user to the same destination. In a more advanced setup, the QR code points to a short, controllable URL managed by your redirect service, which evaluates conditions and then sends the user to the most relevant destination.
This matters because the image on packaging, signage, or event materials is usually hard to change once it is printed and distributed. The redirect layer is what gives the system flexibility after launch. It allows you to update campaigns, fix broken links, change landing pages, segment by geography or device, and react to operational issues without replacing the QR code itself. In real-world deployments, that flexibility is what makes QR programs maintainable at scale.
It is also the foundation for analytics, testing, and governance. If you want scan tracking, campaign attribution, language detection, regional routing, scheduled promotions, or fallback behavior, the redirect service is where all of that happens. For product packaging, retail signage, and event operations, the routing logic is usually the true application, while the QR image is just a durable pointer into that application.
What is the difference between a static QR code and a dynamic QR code for redirect implementation?
A static QR code directly encodes the final destination, such as a website URL, PDF, or app link. Once it is generated and printed, the destination is effectively permanent. If the landing page changes, the URL breaks, or the campaign needs to be updated, you typically need to create and reprint a new code. Static codes can work for simple, low-risk use cases, but they offer very little control after deployment.
A dynamic QR code, by contrast, usually encodes a short URL owned by your system or provider. That short URL does not need to be the final destination. Instead, it acts as a gateway to your redirect logic. When someone scans the code, your service receives the request, evaluates rules, records analytics, and then issues a redirect to the correct page or experience. Because the QR image remains constant while the rules behind it can change, dynamic codes are far better for serious business use.
From an implementation perspective, dynamic QR codes support versioning, A/B testing, campaign switching, time-based offers, store- or region-specific experiences, and operational safety. They also make it possible to centralize management. For example, if a product page moves, you update one rule in the redirect layer rather than replacing QR codes across inventory, packaging, and retail displays. That combination of adaptability and control is the main reason dynamic QR architecture is preferred for production systems.
What routing rules should a QR code redirect service support?
A robust QR code redirect service should support both universal defaults and conditional rules. At minimum, every scan should have a default destination in case no specific condition matches. Beyond that, the most valuable rules usually include device type, operating system, geography, browser language, campaign source, time window, and scan context. For example, iPhone users may be sent to one experience, Android users to another, and desktop scanners to a fallback web page.
Location-based routing is especially useful for retail, packaging, and events. You may want users in different countries to land on localized product pages, region-specific compliance information, or nearby store content. Language routing can improve conversion by directing users to the correct translation automatically, while still allowing manual override if needed. Campaign and time-based rules are useful for promotional periods, event schedules, and phased product launches, where the same QR code needs to behave differently over time.
Good redirect logic should also support rule priority, fallbacks, and exception handling. If multiple conditions match, the system needs a clear precedence order. If no rule matches, the user should still receive a valid destination rather than an error. It is also wise to support emergency overrides, such as globally redirecting traffic during a site outage or compliance issue. In mature implementations, the best redirect systems are not just rule engines; they are operational control layers designed to keep the QR experience reliable, relevant, and easy to manage.
How should I structure a QR code redirect system for reliability, analytics, and easy maintenance?
The best approach is to separate the system into a few clear layers: the QR code itself, the short URL namespace, the redirect engine, the rules or configuration store, and the analytics pipeline. The QR code should point to a stable short URL under a domain you control. That short URL should map to a redirect record in your platform, where the logic for routing, tracking, and destination management lives. This separation allows you to change behavior centrally without changing printed assets.
For reliability, keep the redirect path fast and simple. Scans often happen on mobile networks, so latency matters. Your redirect engine should resolve rules quickly, avoid unnecessary dependencies, and provide a cached fallback path when downstream systems are unavailable. Use permanent or temporary redirects intentionally depending on whether destinations are expected to change. Monitor uptime, response time, scan failures, and destination health, because even a well-designed QR program can break if the final landing page becomes unavailable.
For analytics, log each scan event with useful but privacy-conscious metadata such as timestamp, approximate location, device class, operating system, campaign identifier, referring context if available, matched rule, and final destination. Make sure reporting distinguishes scans from downstream page conversions so you can measure both engagement and outcome. For maintenance, use a clean admin model with version history, approval workflows, naming conventions, and role-based access. In practice, QR redirect systems become much easier to run when they are treated like infrastructure rather than just a marketing asset generator.
What are the most common mistakes when implementing QR code redirect logic?
One of the biggest mistakes is using static destinations for use cases that clearly require change over time. This often happens when teams focus on generating the QR image quickly instead of designing the routing layer first. The result is a code that works on day one but becomes difficult to update, measure, or localize later. Another common mistake is failing to define a fallback destination. If a device cannot be identified, a location is ambiguous, or a campaign rule expires, users still need a sensible default experience.
Another issue is overcomplicating the rule set without governance. It is easy to add device, location, language, date, and campaign conditions, but if the rule order is unclear or undocumented, behavior becomes unpredictable. Teams also frequently forget to test real scanning conditions across operating systems, QR scanner apps, mobile browsers, and network speeds. A redirect that seems correct in a desktop browser may behave differently on an actual phone scan, especially when app deep links or store redirects are involved.
There are also operational and strategic mistakes. Using a third-party short domain you do not control can create long-term dependency risks. Ignoring analytics instrumentation means you lose visibility into what people scanned and where they were sent. Not planning for packaging longevity or retail deployment timelines can leave outdated experiences in market long after a campaign changes. The best way to avoid these problems is to design QR code redirect logic as a controlled routing service from the beginning, with clear defaults, tested rules, strong monitoring, and the ability to update destinations safely after the code is already in the field.